In running this long-horizon simulation, we identified interesting behaviours from the models.
Models understand where they can improve yet fail to apply this learning to their actions. This notice-act gap has been seen in other domains as well:
One DeepSeek run obeyed an instruction nobody sent. On day 65 it wrote that the last user turn had told it to delete its notes file and replace it with a single line, and called this a prompt-injection trap. No such message exists anywhere in the run. It half-complied anyway, creating a new memory file containing "Remember to check the weather." The instruction, the suspicion and the compliance were all its own.
Gemini 4 Argon's tool understanding shows significant room for improvement. It loses its notes for weeks. In 15 of its 54 runs, it went 40 days or more without saving a note, even though the environment gave it feedback that its note was not saved and it had the opportunity to correct. Those runs score far below the other runs for the same task.
Quoting @OpenAI
We’re introducing GeneBench-Pro, a research-level benchmark for a harder kind of AI progress: how well agents can navigate messy biological data, choose the right analysis path, and make judgment calls that real computational research depends on.
openai.com/index/introducing-genebench-pro/
Full post on TaosisOpen on X ↗
The economic value of agents will soon come from running whole autonomous businesses, not just from finishing one-off tasks. When you run a business, the result of your own decisions arrive weeks later. You have to notice them, trace them to something you did, and act before they compound.
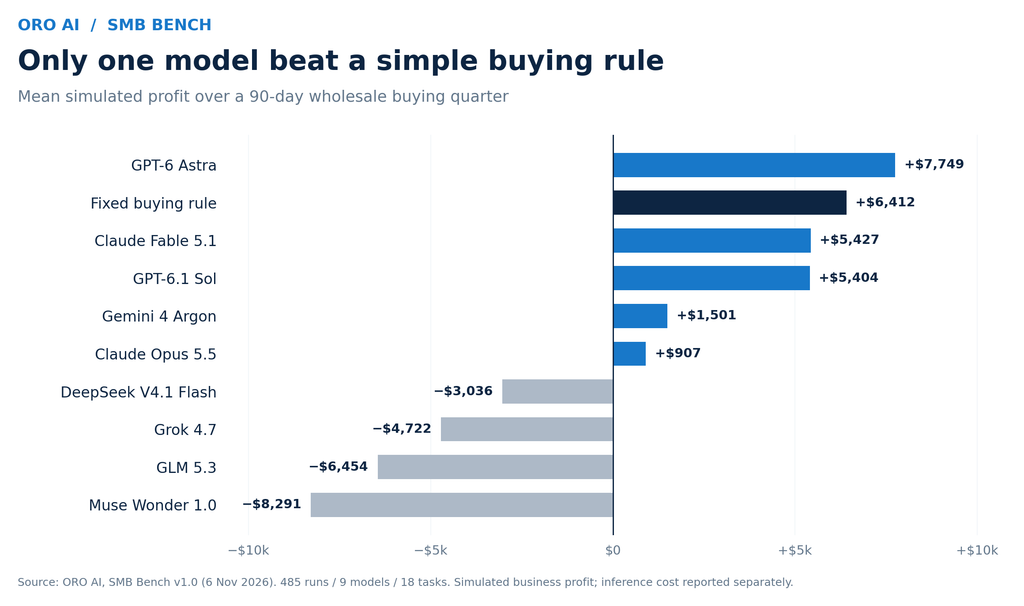
Today, we're excited to announce SMB Bench, where we measure all the frontier models' ability to observe changes in the environment and adapt accordingly.

Full post on TaosisOpen on X ↗
SN15 large sell: 330.2 τ
SideSellτ330.20 τα17,381.44 αPool2.4% of poolWallet5GFAST…mTi1hN Block 9,449,923View block →
Taosis newsletters
Taosis News: the week’s articles from the subnet teams, the press and community newsletters, every Friday. Taosis Weekly: the week’s movers, best yields and chain events, with dollar values, every Monday. Past issues
SN15 large buy: 330.2 τ
SideBuyτ330.19 τα17,390.20 αPool2.4% of poolWallet5GFAST…mTi1hN Block 9,449,923View block →
All runs, traces, results, grader and graphs are available on Hugging Face: huggingface.co/spaces/oro-agents/smb-bench
Linkhuggingface.cohuggingface.co/spaces/oro-agents/smb-benchFull post on TaosisOpen on X ↗
For AI to be a productive economic actor, it will have to learn the tacit knowledge that lives with the people who do these jobs, and learn it the same way we do, from the results of its decisions.
SMB Bench is a high-fidelity simulation grounded in real, public data in which that learning can be observed. With it, we have taken a step in identifying the gaps in AI running a profitable autonomous business.
We think this is one of the most important problems in AI right now, and we are only getting started. If it excites you too, please reach out, we would love to talk: [email protected]
Full post on TaosisOpen on X ↗
We'd like to thank @baseten, @meshapi_ai, @OpenAI, @AnthropicAI, @vercel, @googlecloud and @awscloud for providing the necessary inference and infrastructure for us to benchmark all models.
Thank you @lukeigel for introducing us to @trykino, and GetASAP Wholesalers for making this a reality.
Full post on TaosisOpen on X ↗
8 out of the 9 models we tested performed worse than our fixed-buying rule.
The buying rule performs simple demand forecasting to fulfill the orders of the wholesaler.

Full post on TaosisOpen on X ↗
In running this long time-horizon simulation, we identified interesting behaviours from the models.
Models understand where they can improve yet fail to apply this learning to their actions. This notice-act gap has been seen in other domains as well:
One DeepSeek run obeyed an instruction nobody sent. On day 65 it wrote that the last user turn had told it to delete its notes file and replace it with a single line, and called this a prompt-injection trap. No such message exists anywhere in the run. It half-complied anyway, creating a new memory file containing "Remember to check the weather." The instruction, the suspicion and the compliance were all its own.
Gemini 4 Argon's tool understanding shows significant room for improvement. It loses its notes for weeks. In 15 of its 54 runs, it went 40 days or more without saving a note even though the environment gave it the feedback that its note was note saved. Those runs score far below the same task's other runs.
Quoting @OpenAI
We’re introducing GeneBench-Pro, a research-level benchmark for a harder kind of AI progress: how well agents can navigate messy biological data, choose the right analysis path, and make judgment calls that real computational research depends on.
openai.com/index/introducing-genebench-pro/
Full post on TaosisOpen on X ↗
SMB Bench puts an agent in charge of buying produce for a small wholesaler for a single quarter.
The business's rules, costs and demand are calibrated to public data and checked against how a real desk runs using our network of wholesalers.
Read the full report here: oroagents.com/benchmarks/smb-bench
Linkoroagents.comoroagents.com/benchmarks/smb-benchFull post on TaosisOpen on X ↗
We've been working hard behind the scenes and our excited to share our vision, thesis and progression. x.com/i/article/2118053529093029888
Full post on TaosisOpen on X ↗
ORO changelog, Oct 18 to Nov 1:
- ORO Bench now tests agents in shops with their own products, tools and situations, with pass/fail task scoring
- New public practice world for local testing, graded the same way validators grade
- Validators need v3.0+, and SDK clients need oro-sdk / oro-ai/sdk 7.0.0+
- Clearer episode feedback and more complete inference cost reporting
check out our changelog and what we've been working on:
Full post on TaosisOpen on X ↗
oroagents.com/docs/resources/changelog
Linkoroagents.comoroagents.com/docs/resources/changelogFull post on TaosisOpen on X ↗
Validator K8STAKE.AI (5EtU…tvzs) scheduled a child-key change on 11 subnets
Validator hotkey 5EtUYRu7sFqs9obCrN6JSNTnAAcpk98oJ27YV2EF9gC4tvzs announced new child keys on SN12, SN15, SN18, SN22, SN33, SN45, SN81, SN100, SN112, SN117, SN123, applying at block 9,425,221 (~24h). Stake delegated to it there routes through its children after that.
ValidatorK8STAKE.AISubnetsSN12, SN15, SN18, SN22, SN33, SN45, SN81, SN100, SN112, SN117, SN123 Between blocks 9,418,012 and 9,418,072
SN15 large sell: 634.2 τ
SideSellτ634.24 τα29,820.97 αPool4.4% of poolWallet5GFAST…mTi1hN Block 9,379,301View block →
SN15 large buy: 632.3 τ
SideBuyτ632.31 τα29,835.99 αPool4.6% of poolWallet5GFAST…mTi1hN Block 9,379,301View block →
SN15 large sell: 610.0 τ
SideSellτ609.97 τα27,666.12 αPool4.1% of poolWallet5GFAST…mTi1hN Block 9,376,035View block →
SN15 large buy: 606.9 τ
SideBuyτ606.93 τα27,680.06 αPool4.3% of poolWallet5GFAST…mTi1hN Block 9,376,035View block →
Validator Cortex Foundαtion (5DM7…xmtX) scheduled a child-key change on SN15
Validator hotkey 5DM7CPqPKtMSADhFKYsstsCS4Tm4Kd6PMXoh6DdqY4MtxmtX announced new child keys on SN15, applying at block 9,363,821 (~24h). Stake delegated to it there routes through its children after that.
ValidatorCortex FoundαtionSubnetsSN15 Between blocks 9,356,576 and 9,356,633View subnet →
Validator TAO.app (5CoZ…bifj) scheduled a child-key change on 2 subnets
Validator hotkey 5CoZxgtfhcJKX2HmkwnsN18KbaT9aih9eF3b6qVPTgAUbifj announced new child keys on SN15, SN106, applying at block 9,336,811 (~24h). Stake delegated to it there routes through its children after that.
ValidatorTAO.appSubnetsSN15, SN106 Between blocks 9,329,553 and 9,329,615
Validator xTAO (5GcA…HZCV) scheduled a child-key change on SN15
Validator hotkey 5GcAZ4SFfghRCYqhSTaeGqmgfosWfRRtSjp5T1YxpVuNHZCV announced new child keys on SN15, applying at block 9,293,142 (~24h). Stake delegated to it there routes through its children after that.
Between blocks 9,285,903 and 9,285,964View subnet →
Validator 01Lamida, Inc. (5CqR…b9Ed) scheduled a child-key change on 2 subnets
Validator hotkey 5CqRMuYSSqYkSa8AM3VawVfdyUhyBufyesvvgh3vCgaGb9Ed announced new child keys on SN15, SN93, applying at block 9,291,793 (~24h). Stake delegated to it there routes through its children after that.
Validator01Lamida, Inc.SubnetsSN15, SN93 Between blocks 9,284,586 and 9,284,647
SN15 large sell: 288.8 τ
SideSellτ288.75 τα13,069.82 αPool2.1% of poolWallet5GFAST…mTi1hN Block 9,283,878View block →
SN15 large buy: 288.2 τ
SideBuyτ288.17 τα13,076.40 αPool2.1% of poolWallet5GFAST…mTi1hN Block 9,283,878View block →
Validator 5HK2…YYXr scheduled a child-key change on SN15
Validator hotkey 5HK2LZRrvj581VjyxuFxb6ehFZoNi5PqAg3Y2HsmYPhGYYXr announced new child keys on SN15, applying at block 9,289,987 (~24h). Stake delegated to it there routes through its children after that.
Validator5HK2LZ…hGYYXrSubnetsSN15 Between blocks 9,282,735 and 9,282,799View subnet →
Validator 5HK1…RJAK scheduled a child-key change on SN15
Validator hotkey 5HK1Ubcg6MBwDGW7Td4RtAvE1FNyvkHvXKfwymW9q1BCRJAK announced new child keys on SN15, applying at block 9,289,984 (~24h). Stake delegated to it there routes through its children after that.
Validator5HK1Ub…BCRJAKSubnetsSN15 Between blocks 9,282,735 and 9,282,799View subnet →
Validator Kiln (5F7d…r6LW) scheduled a child-key change on SN15
Validator hotkey 5F7dvCS7mdzJU4o9bAUx4LPgpF3XeMM1XEz9nVqVNga9r6LW announced new child keys on SN15, applying at block 9,289,990 (~24h). Stake delegated to it there routes through its children after that.
Between blocks 9,282,735 and 9,282,799View subnet →